Crawled, Currently Not Indexed? A Next.js Developer's Fix List
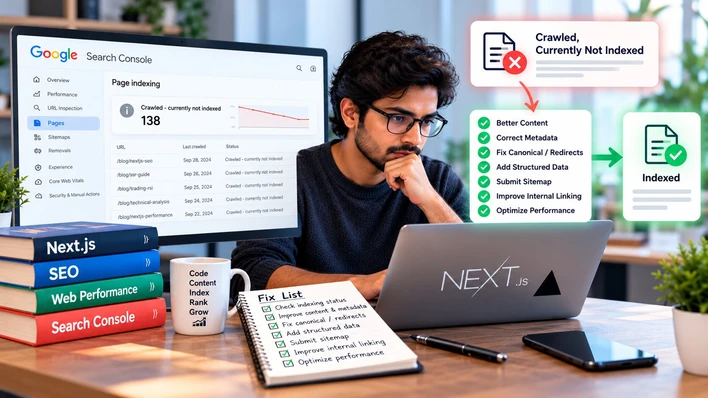
If you open Google Search Console and see "Crawled – currently not indexed" next to some of your Next.js pages, it is tempting to treat it as a bug. It usually is not. Google fetched the page, looked at it, and decided it was not worth adding to the index right now. That is a quality and clarity signal, not an error code.
The good news is that most causes are fixable from the codebase. Below is the checklist I would walk through for a typical Next.js site, in the order that tends to save the most time.
1. Read what Google is actually telling you
Before changing anything, open the page in the URL Inspection tool and compare the live version with what Google last saw. Then open the Page indexing report and look at which URLs share the status. Patterns matter. If every affected URL is a category page, or every one has a similar slug, you have found your lead. The Page indexing report documentation explains each status in plain terms.
2. Check for thin or empty pages
This is the most common cause on directories, marketplaces and blogs with many tag or category pages. A listing page with no items, a tag with one short post, or a template with only a heading and a "nothing here yet" message gives Google very little to index. It also dilutes the rest of your site.
You have two honest options: add real content, or keep the page out of the index until it has some. In the App Router you can decide this per page:
export async function generateMetadata({ params }) {
  const { slug } = await params;
  const itemCount = await getPublishedItemCount(slug);

  return {
    title: `${slug} listings`,
    alternates: { canonical: `https://example.com/category/${slug}` },
    // Empty pages stay crawlable but are not indexed
    robots: itemCount === 0 ? { index: false, follow: true } : undefined,
  };
}
When a page gains content, the noindex disappears on its own the next time it renders.
3. Look for canonicals that point somewhere else
A subtle mistake is setting a default canonical in the root layout. Any page that does not override it will then tell Google that the homepage is its canonical version, and Google may quietly skip those pages. Set the canonical per page, and make it the absolute, final URL: correct protocol, no tracking parameters, no trailing-slash inconsistencies. Google's guide to consolidating duplicate URLs covers the signals it weighs.
4. Keep your sitemap honest
A sitemap is a list of URLs you want indexed, not a list of every URL that exists. Include only pages that return a 200 status, are canonical, and are allowed by robots.txt and your meta tags. A few habits help:
Do not list pages that are noindexed or blocked in robots.txt. Mixed signals waste trust.
Use a real last-modified date from your data. Stamping every URL with the current time on each request teaches Google to ignore the field.
Leave out login, register, search results and other utility pages.
5. Make sure the content is in the HTML
Google can render JavaScript, but rendering is slower and less predictable than reading HTML. If your main content only appears after a client-side fetch, some pages may look empty at crawl time. Fetch data in a server component, or use static generation where it fits, and check the result with "View source". The headline, the body text and the internal links should all be visible there.
6. Validate structured data, and escape it
JSON-LD helps Google understand a page, but it must match what visitors can see. Do not mark up reviews, ratings or prices that are not on the page. There is also a security detail developers often miss. If you inject JSON-LD with dangerouslySetInnerHTML, a value such as a search term or review that contains the text </script> can break out of the script tag. Escape the angle brackets when you serialise:
const safeJsonLd = (data: unknown) =>
  JSON.stringify(data).replace(/</g, "\u003c");
It is a one-line change and the output stays valid JSON.
7. Give every page a way in
Pages that nothing links to are called orphans, and Google tends to treat them as unimportant. Add breadcrumbs, link from parent pages to their children, and show related items at the bottom of detail pages. Plain text links in the HTML are enough. Internal links also tell Google which pages you consider important.
8. Clean up near-duplicates
If your data contains two records for the same thing, with slugs like aadhaar-services and aadhaar-services-1, Google will often choose one and drop the other. Merge the duplicates, redirect the old URL with a 301, and update internal links. The same goes for pages that share the same templated description with only one word changed. Unique titles and descriptions are worth the effort.
9. Do not forget speed and stability
Core Web Vitals will not rescue a thin page, but slow, unstable or error-prone pages are crawled less and judged less favourably. Optimise your largest image, avoid layout shifts, and keep server errors out of your logs. Treat performance as a baseline rather than a trick.
10. After you fix it
Deploy the changes and confirm them with URL Inspection.
Resubmit the sitemap in Search Console.
Use "Request indexing" for a handful of your most important pages. Do not spam it.
Click "Validate fix" in the Page indexing report and be patient. Reprocessing can take days or weeks.
A quick checklist
Does each indexed page have unique, useful content?
Is the canonical correct on every page?
Does the sitemap list only indexable URLs?
Is the main content present in the server-rendered HTML?
Is structured data accurate and safely escaped?
Does every page have internal links pointing to it?
Have you merged duplicate pages?
Final thoughts
"Crawled – currently not indexed" feels frustrating because it gives no reason. But it is Google telling you the page has not yet earned a place in the index. Make each page clearly distinct, clearly useful and easy to reach, and the status tends to resolve itself. Fix the pattern behind the pages, not each page one by one, and you will save a lot of time.


Comments (0)
No comments yet. Be the first to comment!